
3 Hidden Ways Training Data Can Make Artificial Intelligence Biased

A language model does not think. It predicts. Given a sequence of words, it calculates which word is most likely to come next, based on patterns it absorbed from billions of sentences written by human beings. That sounds neutral until you remember that human beings have spent centuries writing in ways that reflect who had power, who got published, and whose experiences were considered worth recording.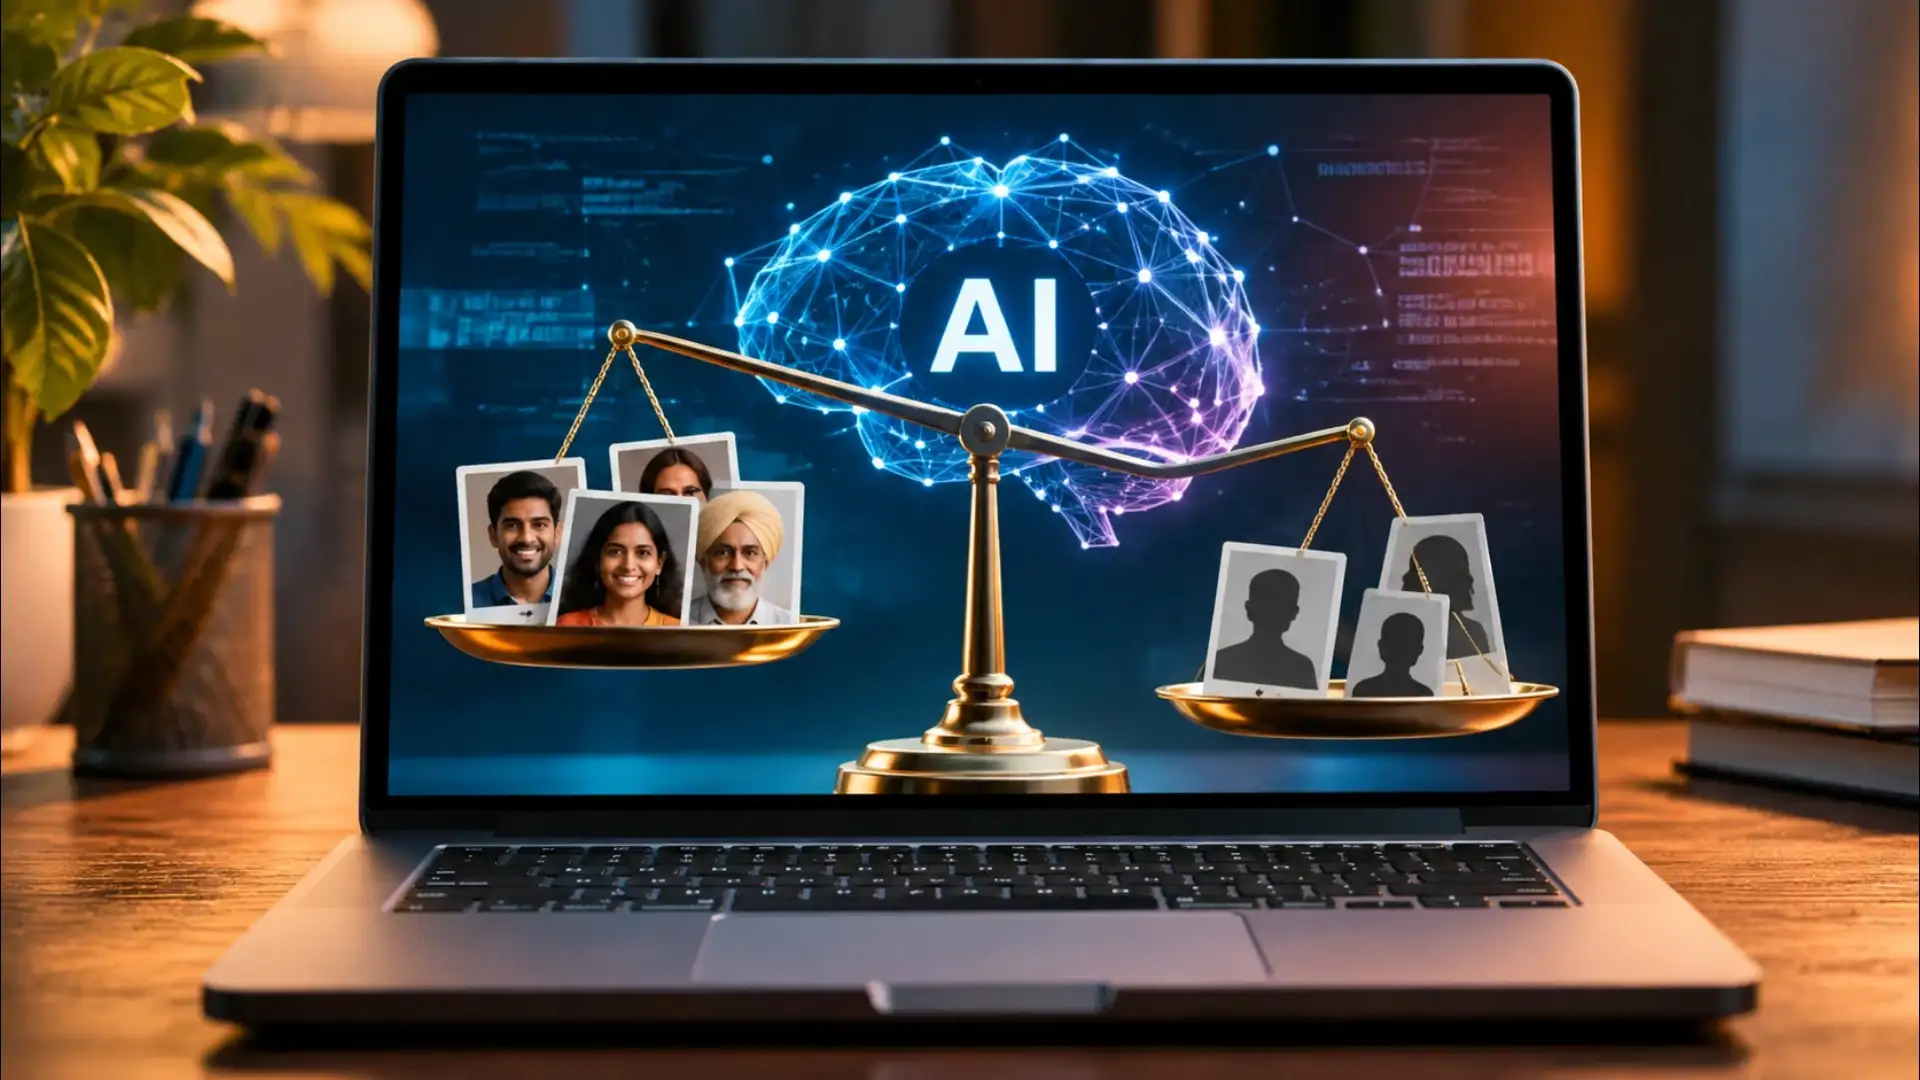
The model sees this corpus and learns what is normal from it. If a particular profession appears overwhelmingly next to one gender across millions of sentences, the model encodes that association as a statistical fact about the world. It is not making a judgement. It is repeating the judgement already embedded in the data.
The same problem appears in crime and lending data. If historical decisions about who was arrested or who was denied a loan were influenced by factors unrelated to actual risk, a model trained to predict future outcomes from that data learns to replicate those patterns. The past discrimination becomes a training signal, not a cautionary tale.
Research on content moderation datasets has found that annotators from different cultural backgrounds rate the same sentence differently, particularly for sarcasm, dialect, and coded language. A model trained on labels produced mostly by one group learns to treat that group's reading as the correct reading. Sentences in African American Vernacular English, for instance, have been flagged as more toxic by models whose training labels came disproportionately from annotators unfamiliar with the dialect.
None of this means AI is irreparably broken. It means the model is a product of the choices made before it was trained, what to collect, what to exclude, and who to trust to label it. Recognising those three entry points turns a user from a passive recipient into a more careful reader of what the model produces and why.
The Dataset Reflects Who Got to Speak
Most large AI models are trained on text scraped from the internet, digitised books, and archived news. Each of these sources carries a built-in selection problem. Internet text skews toward English, toward urban users, toward people who had the time and access to write publicly. Digitised books skew toward works that publishers considered commercially viable or academically important. News archives skew toward events and people that editors judged newsworthy.The model sees this corpus and learns what is normal from it. If a particular profession appears overwhelmingly next to one gender across millions of sentences, the model encodes that association as a statistical fact about the world. It is not making a judgement. It is repeating the judgement already embedded in the data.
Historical Records Carry Historical Prejudice
Training data is not just from the present. It includes decades-old text, court records, medical literature, and social science research produced under conditions that excluded large groups of people from study or from authorship. A medical dataset built from clinical trials that historically enrolled mostly men will produce a model that is less accurate when reasoning about symptoms that present differently in women.The same problem appears in crime and lending data. If historical decisions about who was arrested or who was denied a loan were influenced by factors unrelated to actual risk, a model trained to predict future outcomes from that data learns to replicate those patterns. The past discrimination becomes a training signal, not a cautionary tale.
The Label Is Only as Fair as the Labeller
Many AI systems require human annotators to label training examples, marking an image as containing a dog, rating a piece of text as toxic or harmless, deciding whether a job application is strong or weak. These labels are the ground truth the model tries to learn. They are also human opinions, made quickly, often by workers in a narrow demographic band, under time pressure.Research on content moderation datasets has found that annotators from different cultural backgrounds rate the same sentence differently, particularly for sarcasm, dialect, and coded language. A model trained on labels produced mostly by one group learns to treat that group's reading as the correct reading. Sentences in African American Vernacular English, for instance, have been flagged as more toxic by models whose training labels came disproportionately from annotators unfamiliar with the dialect.
None of this means AI is irreparably broken. It means the model is a product of the choices made before it was trained, what to collect, what to exclude, and who to trust to label it. Recognising those three entry points turns a user from a passive recipient into a more careful reader of what the model produces and why.
Next Story